CoLT5: Reading long documents with selective computation

A practical guide to "CoLT5: Faster Long-Range Transformers with Conditional Computation"
CoLT5: Reading long documents with selective computation cover

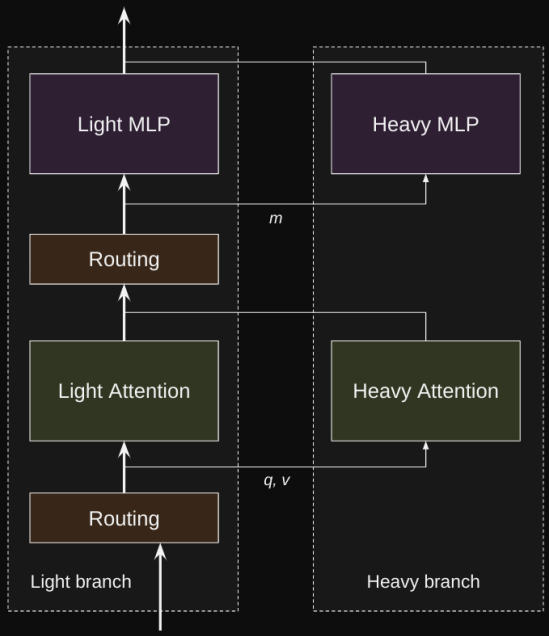
CoLT5 processes every input token with lightweight layers and gives selected tokens additional, higher-capacity computation. This guide explains its learned routing, light and heavy branches, faster decoding, and experiments with inputs up to 64k tokens.

View comments.

more ...

Decision Transformer: Unifying sequence modelling and model-free, offline RL

"Decision Transformer: Reinforcement Learning via Sequence Modeling" - Research Paper Explained
Decision Transformer: Unifying sequence modelling and model-free, offline RL cover

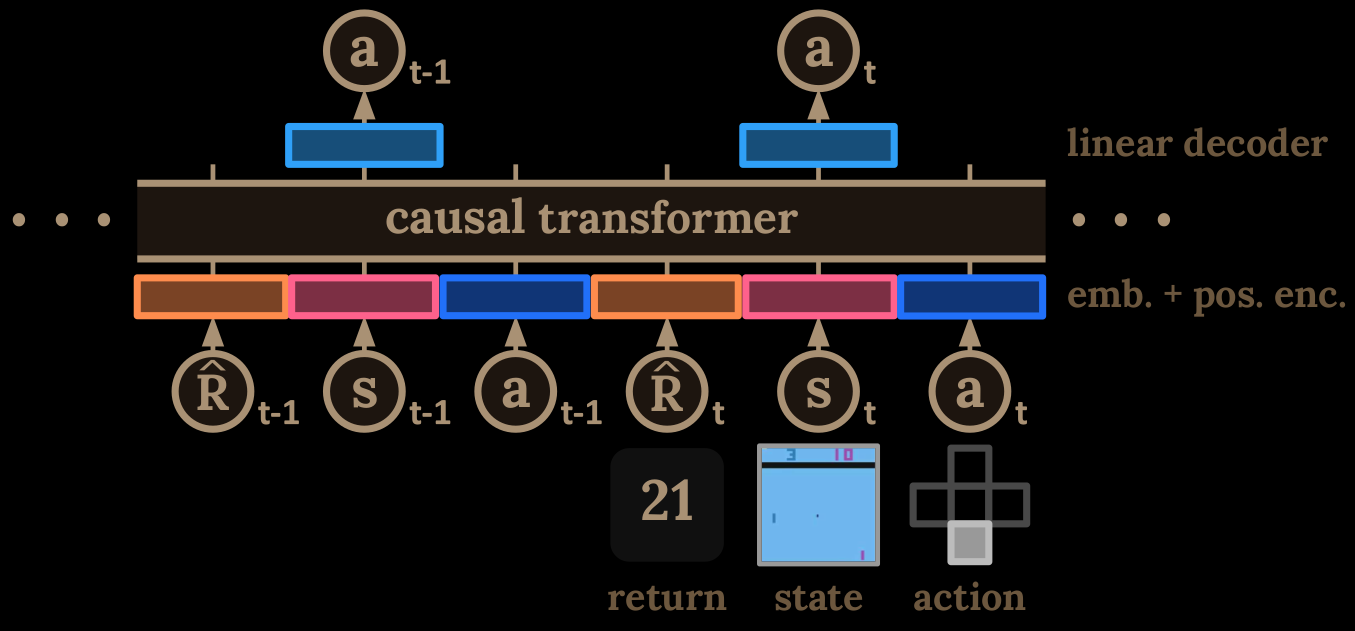
Decision Transformer casts offline reinforcement learning (RL) as conditional sequence modeling. A causally masked GPT-style Transformer predicts each action from a desired return-to-go, the current state, and the recent trajectory. It avoids value-function bootstrapping and policy-gradient optimization during training, yet matches or exceeds several strong offline RL baselines on the benchmarks studied in the paper.

View comments.

more ...

🌀 MLP-Mixer: How image patches communicate without attention

A practical guide to "MLP-Mixer: An all-MLP Architecture for Vision"
🌀 MLP-Mixer: How image patches communicate without attention cover

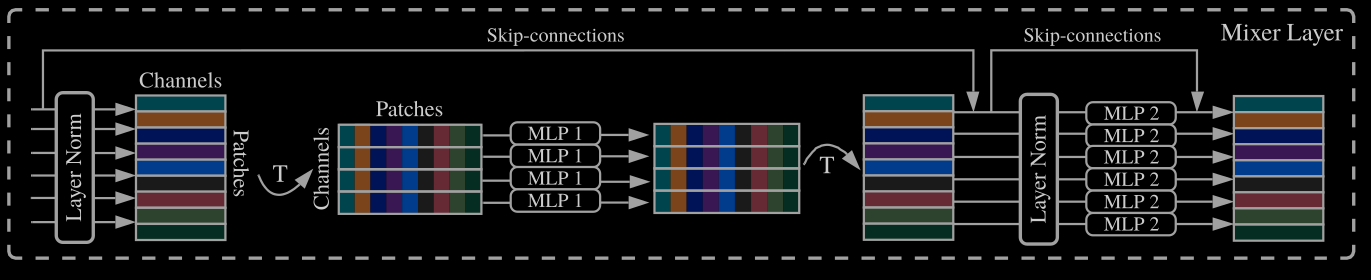
MLP-Mixer classifies images without convolution or self-attention. This guide follows an image through patch projection, token mixing, channel mixing, and classification, then examines the paper's accuracy, throughput, scaling, and permutation experiments.

View comments.

more ...

🦖 DINO: Self-supervised ViTs learn strong features and semantic structure

"Emerging Properties in Self-Supervised Vision Transformers" - Research Paper Explained
🦖 DINO: Self-supervised ViTs learn strong features and semantic structure cover

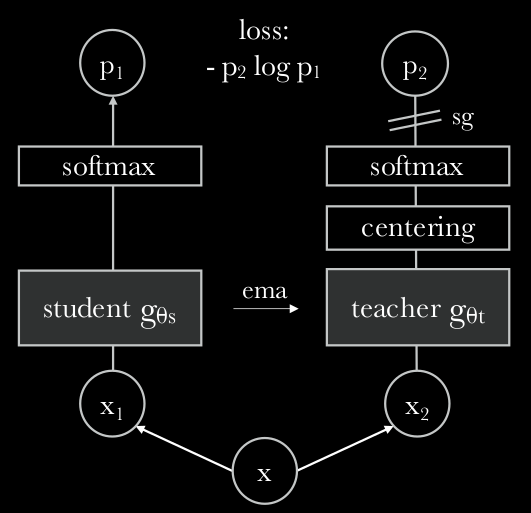
Self-distillation with no labels (DINO) trains a student network to match an exponential-moving-average teacher across differently augmented views of the same image. Applied to Vision Transformers, it produces features that perform strongly with simple linear and k-nearest-neighbor classifiers. Its final-layer self-attention also reveals object boundaries without segmentation labels, although DINO is not itself a segmentation model.

View comments.

more ...

ERNIE 2.0: Continual multi-task pre-training for language understanding

What Baidu's 2019 framework changed, how its seven objectives work, and what its results establish
ERNIE 2.0: Continual multi-task pre-training for language understanding cover

ERNIE 2.0 extends masked-language-model pre-training with seven lexical, structural, and semantic objectives learned continually through a shared Transformer. This guide explains the training schedule, task embeddings, 2019 English and Chinese evaluations, and the limits of the reported comparison with BERT and XLNet.

View comments.

more ...

The Transformer – Attention is all you need.

The Transformer – Attention is all you need. cover

Transformer - more than meets the eye! Are we there yet? Well... not really, but...
How about eliminating recurrence and convolution from transduction? Sequence modeling and transduction (e.g. language modeling, machine translation) problems solutions has been dominated by RNN (especially gated RNN) or LSTM, additionally employing the attention mechanism. Main sequence transduction models are based on RNN or CNN including encoder and decoder. The new transformer architecture is claimed however, to be more parallelizable and requiring significantly less time to train, solely focusing on attention mechanisms.

View comments.

more ...