Michał Chromiak's blog
🎭 Masked autoencoder (MAE) for visual representation learning. From the author of ResNet.
"Masked Autoencoders Are Scalable Vision Learners" - Research Paper Explained
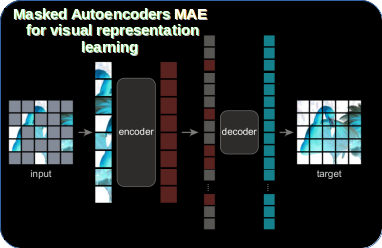
A masked autoencoder (MAE) learns visual representations by reconstructing missing image patches from a small visible subset. It divides an image into regular non-overlapping patches, samples patches uniformly without replacement, removes the masked patches before the encoder, and inserts learned mask tokens only for the lightweight decoder. With a 75% masking ratio, the encoder processes just 25% of the patches. This asymmetric design reduces training time and memory, enabling ViT-Large and ViT-Huge models to scale on ImageNet-1K. A ViT-Huge model pretrained for 1600 epochs and fine-tuned at 448-pixel resolution reaches 87.8% ImageNet-1K top-1 accuracy.
more ...