 Michał Chromiak's blog
BERT showed that a Transformer can learn reusable language representations from large amounts of unlabeled text. ERNIE 2.0 asks a natural follow-up question: must pre-training be organized around only one or two objectives? A corpus contains more than local word co-occurrence. It also contains entities, sentence order, discourse relations, document topics, and weak signals of relevance.
Yu Sun and colleagues at Baidu introduced ERNIE 2.0 in 2019 as a framework for turning several such signals into pre-training tasks. Instead of training every objective separately or restarting whenever a new task is introduced, ERNIE 2.0 adds objectives incrementally and continues multi-task training with a shared encoder.
This article describes the 2019 paper. The name ERNIE has since been reused for later Baidu model families, so claims here should not be projected onto every system carrying that name.
The short version🔗
- ERNIE 2.0 is primarily a training framework, not a radically different sequence architecture.
- Its encoder is a bidirectional Transformer closely related to BERT.
- Seven pre-training objectives target lexical, syntactic, document-level, and discourse information.
- A learned task embedding tells the shared encoder which objective produced the current example.
- New objectives are introduced continually, while older objectives remain in the training mixture to reduce forgetting.
- In the paper's 2019 experiments, ERNIE 2.0 improved over the reported BERT and XLNet baselines across 16 English and Chinese tasks. That is a result under the paper's models, data, and evaluation protocol, not a current state-of-the-art claim.
Why use several pre-training objectives?🔗
A masked language model hides tokens and asks the model to reconstruct them. This is a strong general objective, but the supervision it extracts is indirect. Consider the sentence:
Ada Lovelace worked with Charles Babbage on the Analytical Engine.
Masking a token teaches local and contextual prediction. Other transformations can emphasize different structure: mask the whole entity Ada Lovelace, determine whether two sentences came from the same document, recover shuffled sentence order, or decide whether a query and title are relevant.
ERNIE 2.0 groups its objectives into three families:
- Word-aware tasks emphasize lexical and entity information.
- Structure-aware tasks emphasize relationships between sentences.
- Semantic-aware tasks use document and weakly supervised relevance signals.
These objectives do not install symbolic knowledge into fixed locations. They provide additional prediction problems whose gradients shape the same contextual encoder.
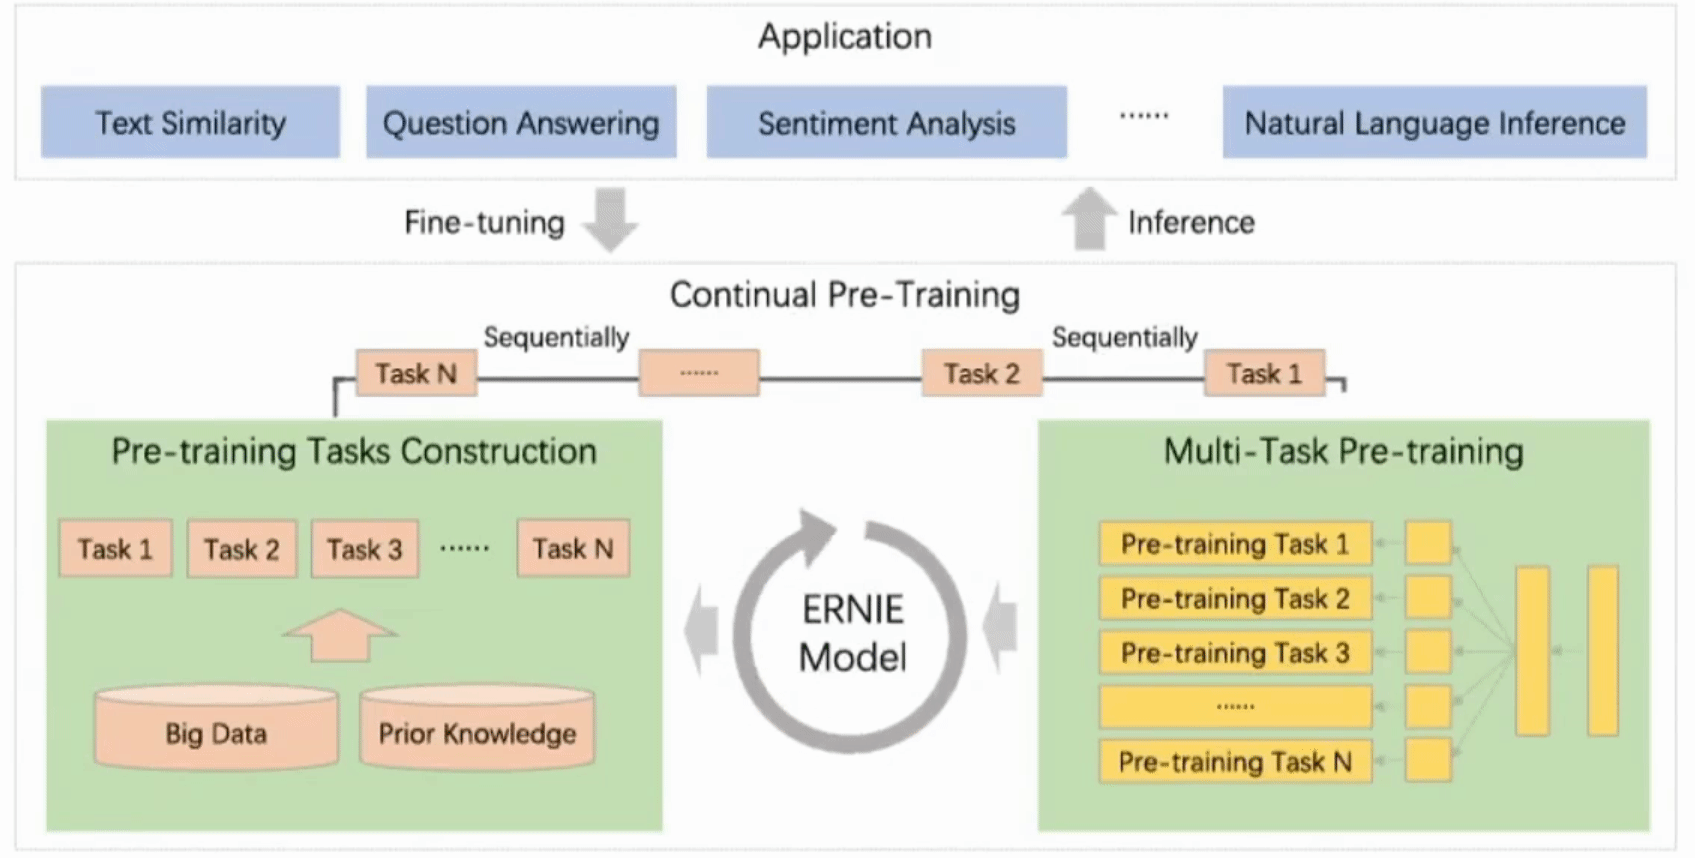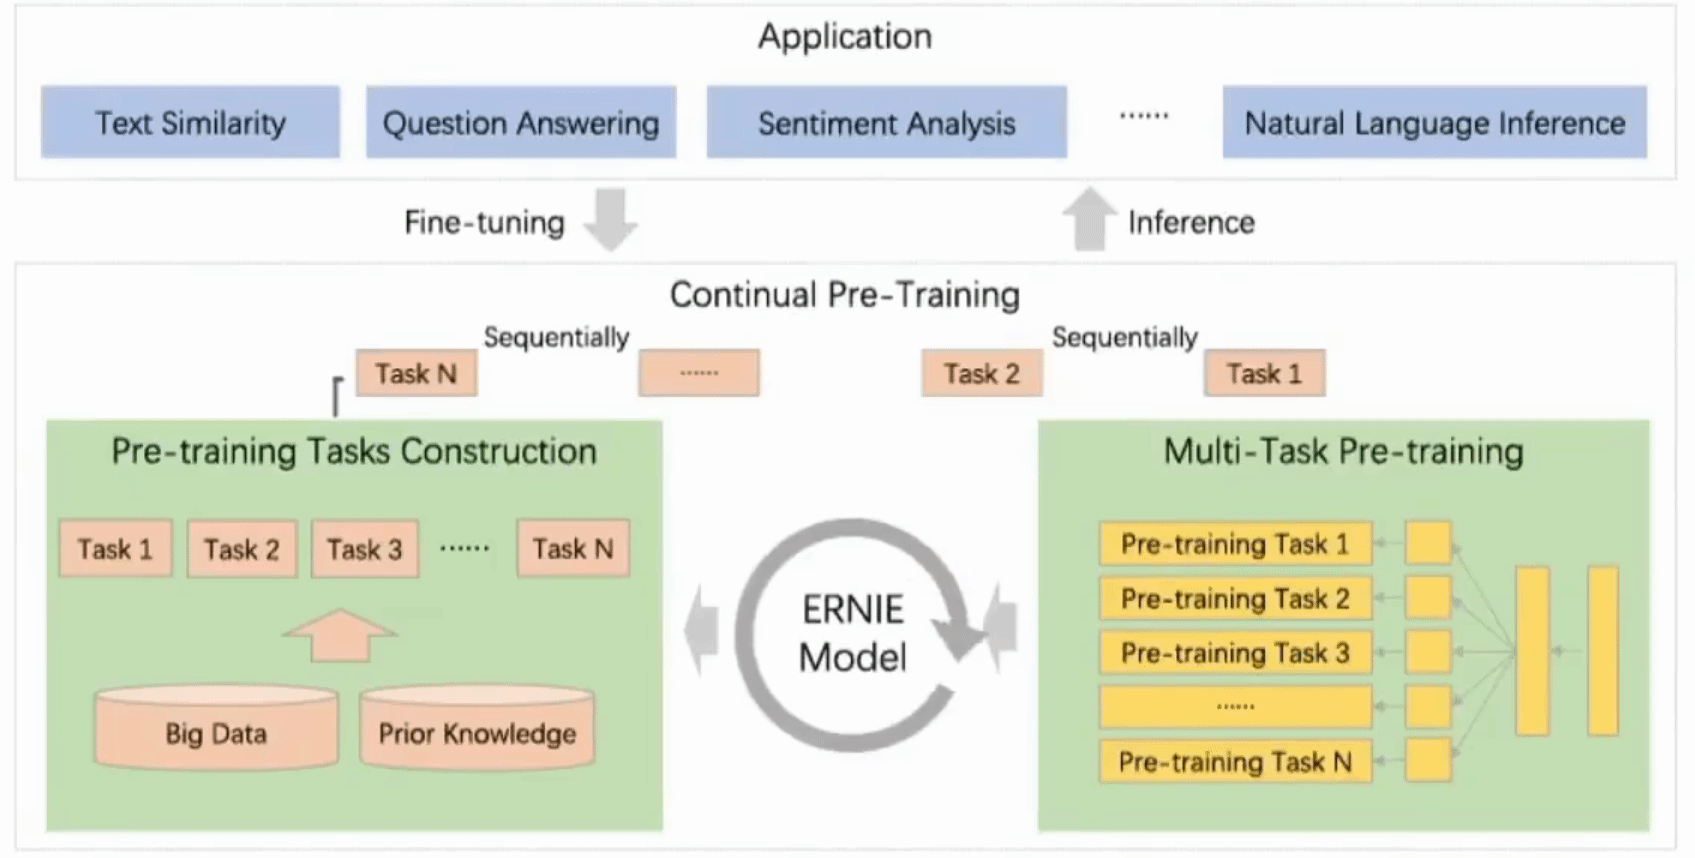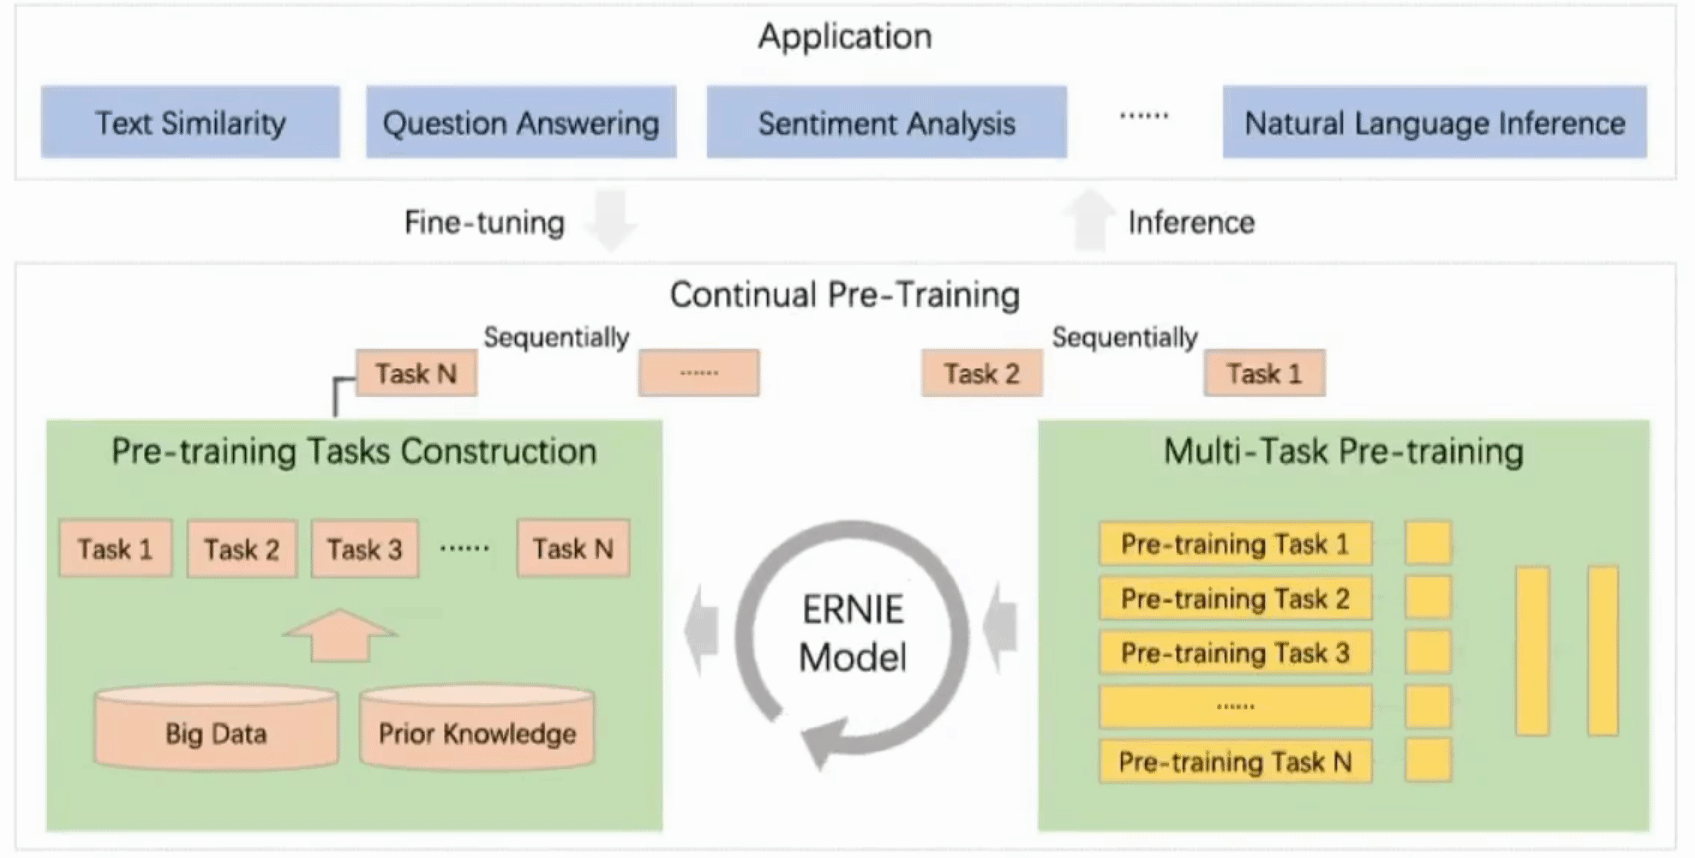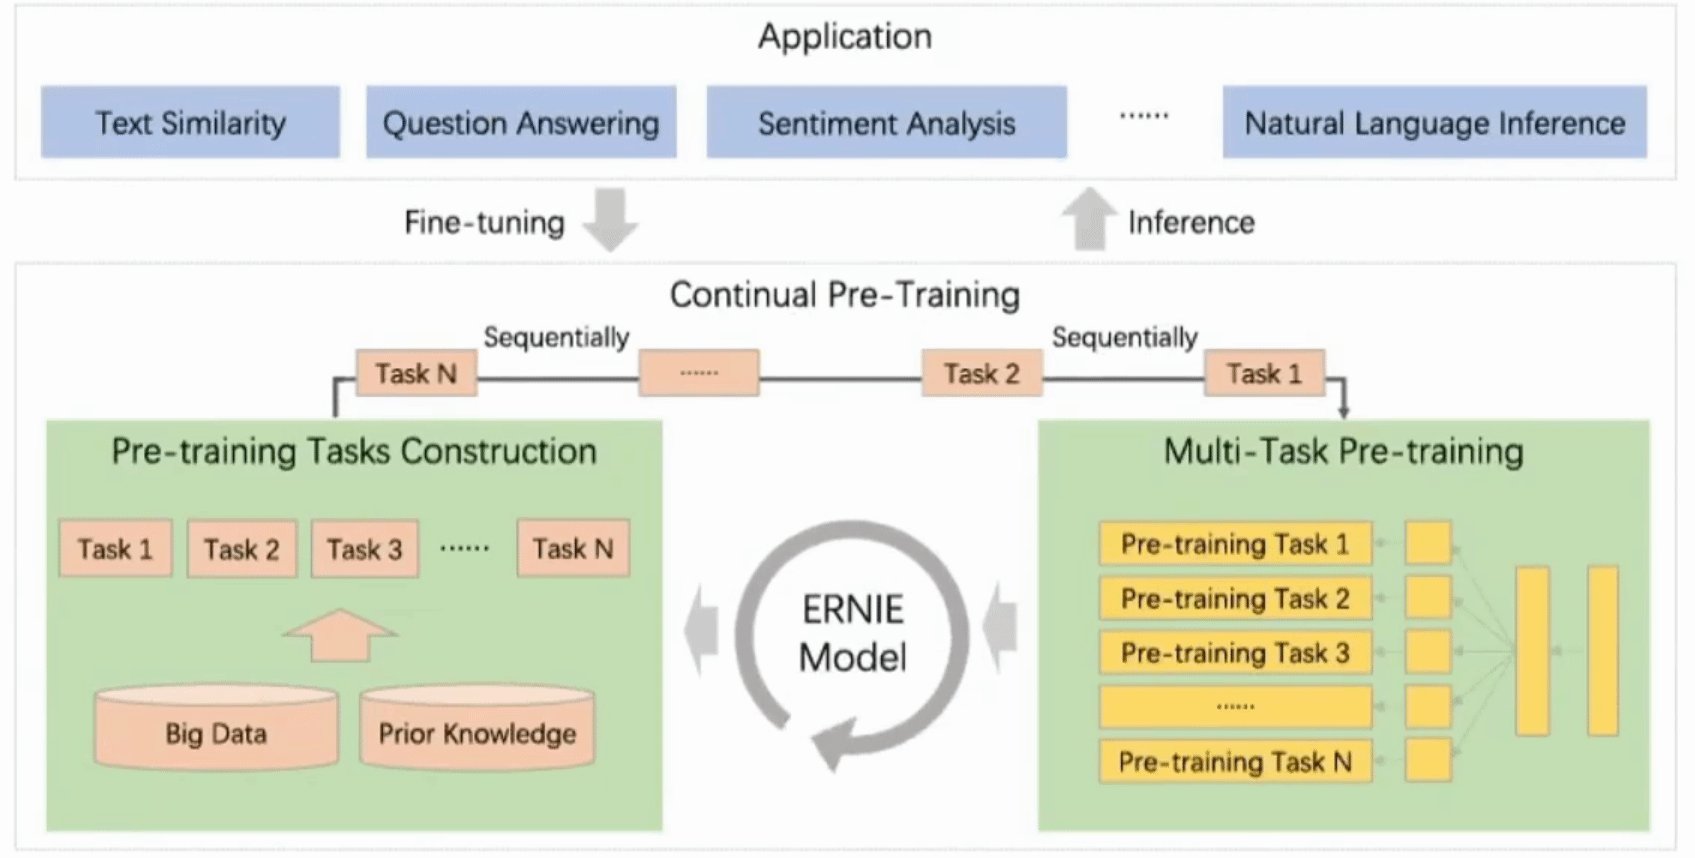
Figure 1. ERNIE 2.0 introduces pre-training tasks over successive stages while retaining earlier tasks in the multi-task schedule. (Source: Sun et al., 2019, Figure 2).
Continual does not mean online learning🔗
In this paper, continual pre-training means that the training curriculum can expand. The first stage trains an initial set of objectives. A later stage initializes from that checkpoint, adds another objective, and trains on the accumulated set.
Keeping earlier tasks matters. If the model optimized only the newest task, it could overwrite representations useful for earlier ones, a failure commonly called catastrophic forgetting. ERNIE 2.0 instead uses continual multi-task learning: old and new objectives share the encoder and remain available during later stages.
Optional detail: What is shared and what is task-specific?
The Transformer encoder parameters are shared across objectives. Each input combines token, segment, position, and task embeddings. The task ID therefore changes the input representation and lets the encoder condition on the current objective.
Prediction heads and losses depend on the task. Token-level objectives predict labels at individual positions; sequence-level objectives classify an entire sentence pair or document relation. Sharing the expensive encoder lets these different signals influence one representation space without requiring a complete model per objective.
The seven objectives🔗
Word-aware objectives🔗
Knowledge masking masks complete phrases and named entities rather than always masking isolated subword tokens. Reconstructing an entire multi-token unit makes the model rely on broader context.
Capitalization prediction asks whether a token was capitalized in the original text. Capitalization can provide weak clues about names and sentence boundaries, although those clues are language- and script-dependent.
Token-document relation prediction asks whether a token appears elsewhere in the source document. The task pushes token representations to retain document-level thematic information.
Structure-aware objectives🔗
Sentence reordering splits a paragraph into segments, permutes them, and asks the model to recover their original order. It targets local discourse structure rather than only token identity.
Sentence distance classifies sentence pairs as adjacent, from the same document but non-adjacent, or from different documents. This supplies a graded notion of textual relatedness.
Semantic-aware objectives🔗
Discourse relation prediction uses explicit discourse markers as weak supervision for relations between clauses or sentences.
IR relevance prediction uses query-title pairs from search data to distinguish relevant from less relevant pairs. This is weakly supervised rather than purely self-supervised because user interactions provide the signal.
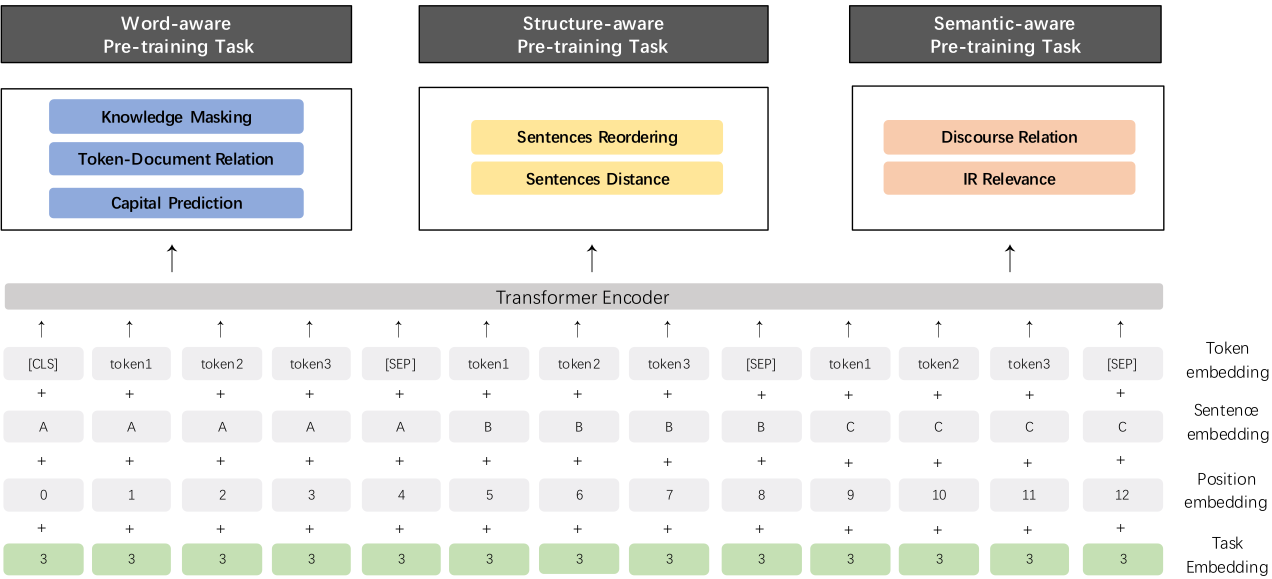
Figure 2. The encoder receives token, segment, position, and task embeddings. Separate objectives reuse the shared Transformer. (Source: Sun et al., 2019, Figure 3).
From pre-training to a downstream task🔗
Pre-training learns a general encoder without labels for the final application. Fine-tuning then adapts that encoder using supervised examples for a task such as natural-language inference, sentiment classification, semantic similarity, named-entity recognition, or question answering.
This separation is important. ERNIE 2.0's seven objectives do not directly solve GLUE or the Chinese evaluation tasks. They construct an initialization that the downstream fine-tuning stage can use.
For readers coming from modern parameter-efficient adaptation, LoRA changes the fine-tuning stage rather than the pre-training curriculum: it freezes the base weights and learns small low-rank updates.
What the experiments show🔗
The authors evaluate English models on GLUE and Chinese models on nine common understanding tasks. The paper reports results for base- and large-sized configurations and compares against contemporary systems, including BERT and XLNet.
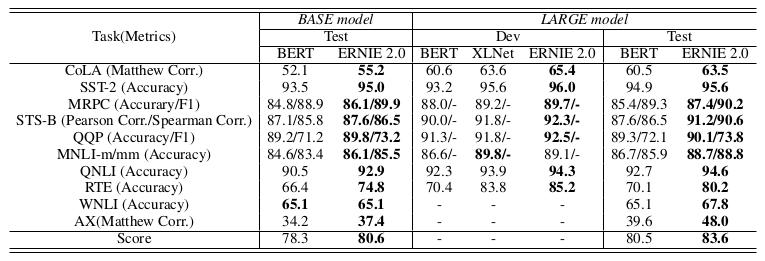
Figure 3. English GLUE results reported in the paper. Scores belong to the paper's 2019 experimental setup and baseline implementations. (Source: Sun et al., 2019, Table 2).
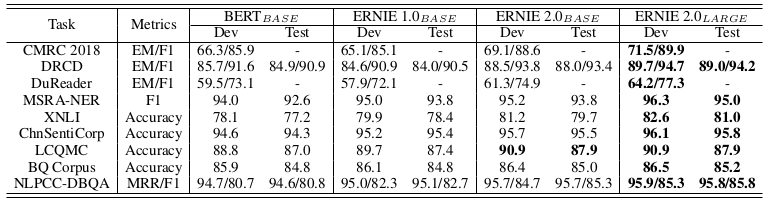
Figure 4. Results reported for nine Chinese language-understanding tasks. The task mixture and corpora differ from the English setup. (Source: Sun et al., 2019, Table 3).
The central empirical claim is that the complete ERNIE 2.0 recipe outperformed the compared BERT and XLNet systems on all 16 evaluated tasks. Ablations also indicate that adding task families improves the aggregate downstream score.
The comparison requires calibration. The systems do not all use identical corpora or pre-training objectives, and benchmark improvements do not isolate a single causal mechanism. The experiments support the value of ERNIE 2.0's combined recipe; they do not prove that every added objective helps every domain or that continually adding objectives will improve without limit.
What aged well🔗
Several ideas remain useful beyond this particular model:
- The objective is part of the architecture. Two models with similar Transformer encoders can learn different representations because their training signals differ.
- Weak supervision can expose structure already present in data. Document boundaries, sentence order, and search interactions can create training labels cheaply.
- Curriculum and retention matter. Adding a task is not enough; the schedule must prevent new learning from erasing useful earlier behavior.
- Multi-task gains need ablations. A larger objective mixture also changes data exposure and optimization, so each contribution should be tested rather than inferred from the final score.
Limitations🔗
- The evaluations measure language understanding benchmarks available in 2019, not generative instruction following or current long-context behavior.
- English and Chinese systems use different corpora and task signals, so the results are not a controlled cross-language comparison.
- Task embeddings tell the encoder which objective it is solving; they do not make the resulting coordinates directly interpretable.
- Continual pre-training still requires replaying earlier objectives and data. It is not continual learning from an unbounded stream at negligible cost.
- The paper predates the scale and evaluation practices of modern foundation models.
Related reading🔗
Start with language-model probability, n-grams, and perplexity for the prediction objective underneath pre-training. The Transformer guide explains the shared encoder architecture. For later adaptation methods, continue with LoRA and QLoRA.
Primary sources🔗
- Yu Sun et al. ERNIE 2.0: A Continual Pre-training Framework for Language Understanding, 2019.
- Baidu/PaddlePaddle. Official ERNIE repository.
Comments
comments powered by Disqus