 Michał Chromiak's blog
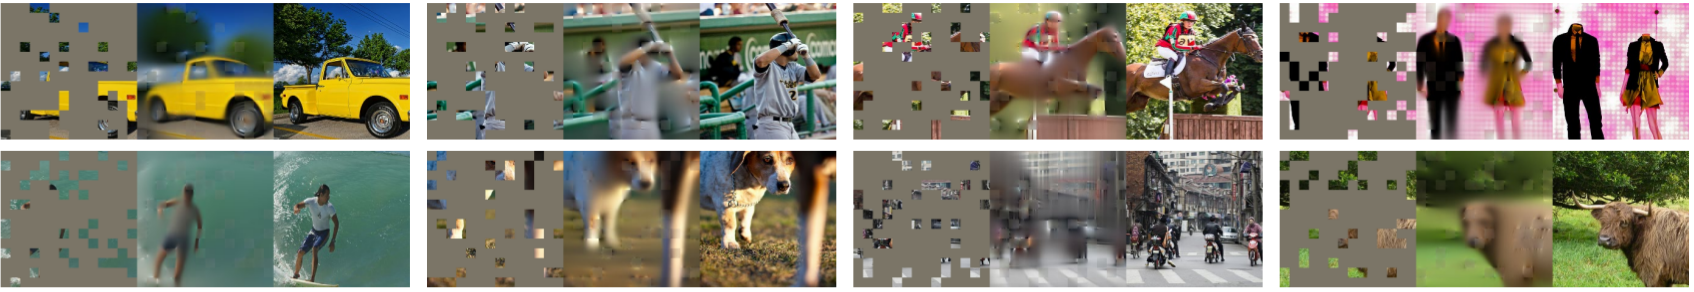 Figure 1. COCO validation images: masked input | MAE reconstruction | ground truth. The MAE model was pretrained on ImageNet-1K, not COCO.
The MAE scalable-learning paper explained🔗
This article explains "Masked Autoencoders Are Scalable Vision Learners" by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, and Ross Girshick. The work first appeared on arXiv on November 11, 2021 and was published at CVPR 2022.
TL;DR🔗
- MAE uses an asymmetric encoder-decoder architecture. With the default 75% masking ratio, the encoder receives only the visible 25% of image patches and no mask tokens.
- After the encoder, a lightweight decoder receives the encoded visible patches plus learned mask tokens placed at the missing positions.
- The decoder predicts the RGB pixel values of every patch, but the mean squared error (MSE) training loss is computed only over masked patches.
- The default decoder uses less than 10% of the encoder's computation per token. It is used only during pretraining and discarded afterward.
- For recognition, the encoder processes the complete, uncorrupted image.
- Excluding mask tokens from the encoder improves ImageNet linear-probe accuracy from 59.6% to 73.5%, a 13.9 percentage-point gain. Fine-tuning accuracy improves from 84.2% to 84.9%.
- Random masking works better than the block-wise and grid-wise alternatives evaluated in the paper.
- MAE does not require two augmented views or negative examples. Its default recipe nevertheless uses random resized cropping and horizontal flipping.
- Under end-to-end ImageNet-1K fine-tuning, MAE outperforms the DINO, MoCo v3, and BEiT results reported in the paper's comparison table. This claim does not extend to every evaluation protocol.
- A ViT-H/14 pretrained for 1600 epochs and fine-tuned at 448-pixel resolution reaches 87.8% ImageNet-1K top-1 accuracy using no external pretraining data.
- The paper reports that MAE is 3.5 times faster per pretraining epoch than BEiT.
Contributions of the paper🔗
- A high masking ratio turns pixel reconstruction into a challenging self-supervised task while reducing the encoder's workload.
- An asymmetric architecture keeps mask tokens out of the large encoder and handles the full token sequence only in a lightweight decoder.
- Direct pixel prediction is competitive with discrete-token targets. Normalizing pixels within each patch improves representation quality.
- MAE works with modest image augmentation. The default is random resized cropping with horizontal flipping; even the center-crop, no-flip ablation remains reasonably effective.
- The efficient recipe scales from ViT-Base to ViT-Huge and transfers well to classification, object detection, instance segmentation, and semantic segmentation.
Motivation🔗
Masking has been highly successful in natural language processing, especially in BERT. Applying related ideas to computer vision was historically less straightforward because convolutional architectures do not naturally operate on sequences of independently removable patches. Vision Transformers (ViTs) make the construction simple: divide an image into patches, hide a subset, and learn to predict the missing content.
Images and language differ in an important way. Language is semantically dense: a missing word generally carries substantial meaning. Images have strong spatial redundancy, so a model can often infer nearby pixels from texture or local continuity. MAE therefore masks a large random fraction of the image, typically 75%, to reduce this redundancy and require a more holistic understanding of objects and scenes.
The reconstruction target is deliberately low-level: pixel values rather than class labels or discrete semantic tokens. The decoder specializes in reconstruction, while the encoder is expected to learn a representation useful for later recognition tasks.
Objective🔗
The objective is to pretrain a reusable visual encoder without labels. After pretraining, the decoder is removed and the encoder is transferred to downstream tasks through linear probing, partial fine-tuning, or full fine-tuning.
Background🔗
ResNet has been highly influential in computer vision and has served as the backbone for self-supervised systems such as BYOL, MoCo, and SimCLR.1
Earlier masked-image approaches often used convolutional networks or more complicated prediction targets. ViT simplified patch-based self-supervision by representing an image directly as a sequence of patch tokens.
BEiT: BERT Pre-Training of Image Transformers, first submitted in June 2021, predicts discrete visual tokens for masked patches. Those targets are produced by a discrete variational autoencoder (dVAE). MAE instead predicts pixels. The paper finds that normalized-pixel targets are statistically comparable to dVAE-token targets across the evaluated ImageNet, COCO, and ADE20K settings, without requiring a separately pretrained tokenizer.
How MAE works🔗
MAE is an autoencoder: an encoder maps the observed input to a latent representation, and a decoder reconstructs the missing part of the input. Its defining feature is that the large encoder operates only on visible patches.
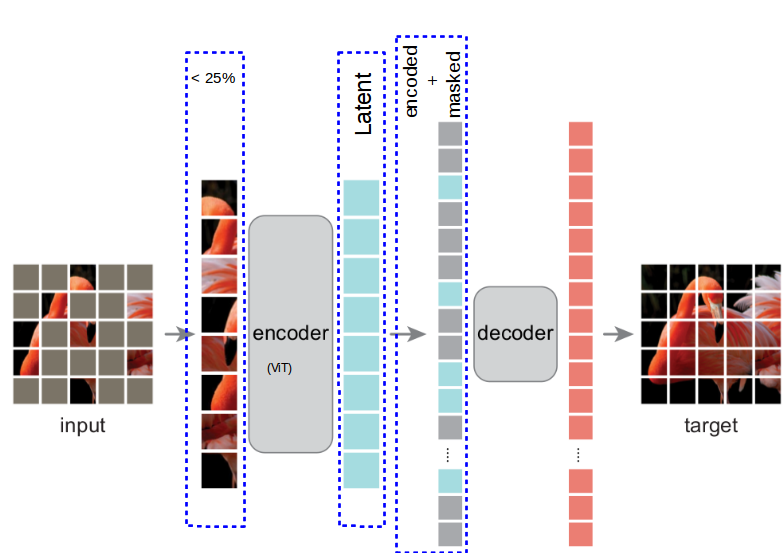 Figure 1a. MAE architecture. This illustration shows fewer than 25% visible patches; the paper's default configuration uses exactly 25% visible patches and masks 75%.
Patch sampling🔗
An image of height \(H\), width \(W\), and \(C\) channels is divided into \(N=HW/p^2\) regular, non-overlapping patches of size \(p\times p\). For each image, MAE samples visible patches uniformly without replacement. The remaining patches are removed from the encoder input.
The default mask ratio is 75%, so the encoder processes exactly 25% of the patch tokens. Other mask ratios are evaluated experimentally; 75% provides the best linear-probe result and is near the top of the fine-tuning range.
Encoder and decoder🔗
The encoder is a standard ViT with linear patch projection, positional embeddings, and Transformer blocks. It receives visible patch embeddings and a class token, but no mask tokens. Processing a quarter of the normal patch sequence substantially reduces computation and memory.
The decoder receives:
- the encoder's representations of visible patches;
- copies of a shared learned mask-token vector for missing positions; and
- positional embeddings that identify every patch location.
The tokens are restored to their original spatial order before passing through the decoder's Transformer blocks. The decoder can be designed independently of the encoder, but its design is not irrelevant: decoder depth strongly affects linear probing, while fine-tuning is less sensitive to it.
The default decoder has eight Transformer blocks with width 512. It uses about 9% of the encoder's FLOPs per token, which the paper summarizes as less than 10%. Because only the lightweight decoder processes the full sequence, the overall pretraining system is efficient.
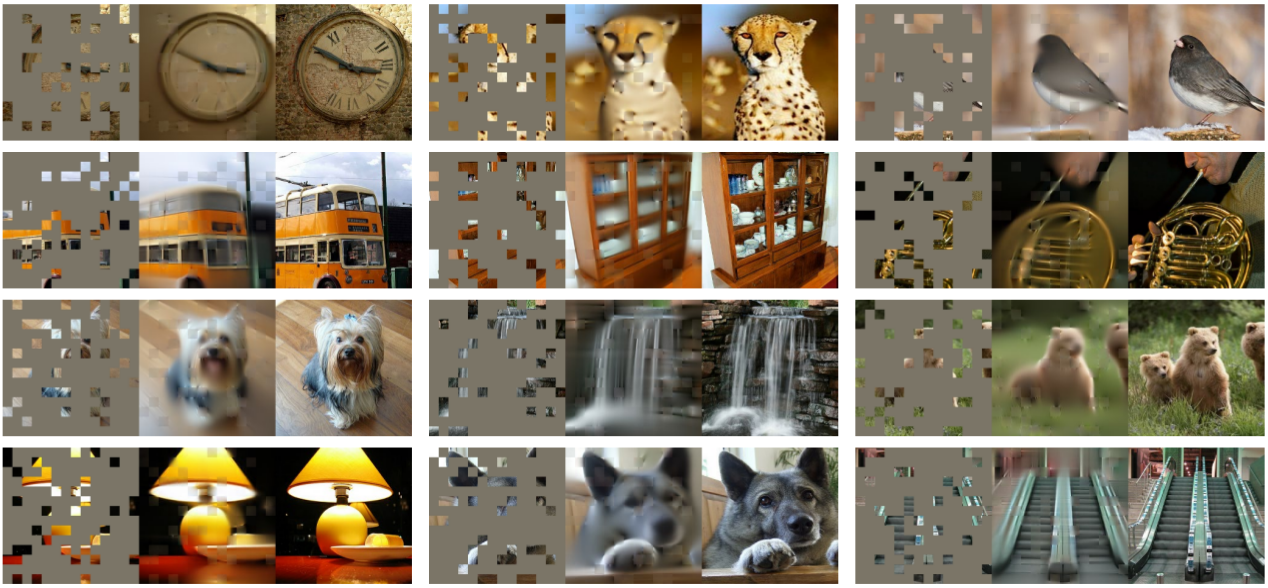 Figure 2. ImageNet validation examples evaluated with an 80% mask ratio: 39 of 196 patches are visible. Masked input | reconstruction | ground truth.
Reconstruction target and loss🔗
For every patch, the decoder outputs a vector with \(p^2C\) channels: one value for every pixel and color channel in that patch. With RGB \(16\times16\) patches, the output dimension is \(16^2\times3=768\) per patch token. The number of decoder output tokens, not the number of output channels, corresponds to the number of image patches.
Let \(M\) denote the set of masked patch indices, \(y_i\in\mathbb{R}^{p^2C}\) the target pixels for patch \(i\), and \(\hat{y}_i\) the corresponding prediction. The paper defines MSE over masked patches in prose. Written explicitly, the official implementation computes:
No loss is applied to visible patches. The authors report that computing loss over all patches slightly decreases downstream accuracy.
The paper also evaluates per-patch normalized targets:
where \(\mu_i\) and \(\sigma_i^2\) are the mean and variance of the pixel values within patch \(i\). Normalized pixels improve the ImageNet fine-tuning result from 84.9% to 85.4% in the 800-epoch ViT-L ablation.
Processing steps🔗
- Divide each image into patches, linearly embed them, and add positional embeddings.
- Randomly shuffle the patch-token list and retain the visible fraction.
- Process only the visible tokens with the encoder.
- Project the encoded tokens to the decoder dimension and append learned mask tokens.
- Unshuffle the full list so visible representations and mask tokens return to their spatial positions.
- Add decoder positional embeddings and process the full sequence with the decoder.
- Predict the pixel vector for every patch and average MSE only over masked patches.
The shuffle and unshuffle operations add negligible overhead and require no specialized sparse operators.
Connections to other architectures🔗
- BERT masks input tokens and predicts the missing tokens. MAE transfers this broad idea to image patches, but uses a much higher masking ratio and predicts pixels.
- GPT uses causal autoregressive prediction rather than BERT-style bidirectional masked-token reconstruction. It is an inspiration for scalable self-supervised pretraining, not a direct architectural analogue of MAE.
- Denoising autoencoders corrupt an input and reconstruct the original signal. MAE is a form of denoising autoencoding, although its sparse encoder and asymmetric decoder differ from classical designs.
- SimCLR and MoCo use contrastive objectives with negative examples. BYOL and DINO avoid explicit negatives but still match representations across augmented views. MAE instead constructs its pretext task through random masking and pixel reconstruction.
MAE relies less heavily on view augmentation than these representation-matching systems, but augmentation is not entirely absent from its default training recipe.
Practical findings🔗
Masking ratio🔗
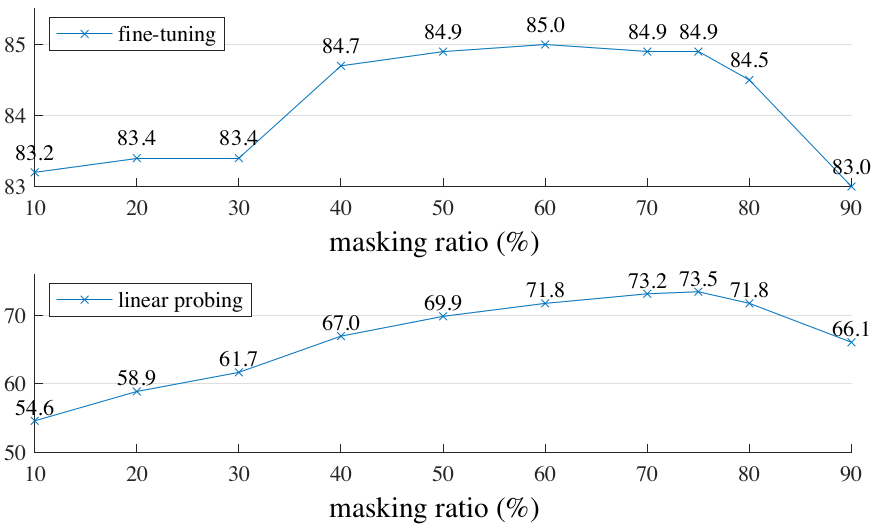 Figure 3. ImageNet fine-tuning and linear-probe accuracy at different masking ratios.
The best masking ratio depends on the evaluation protocol. Linear-probe accuracy peaks at 75% masking with 73.5%. Fine-tuning is less sensitive: ratios from roughly 40% to 80% all perform strongly, with the plotted maximum of 85.0% at 60%.
The reconstructions below illustrate how outputs change when the same model, pretrained with 75% masking, is evaluated with 75%, 85%, and 95% masking.
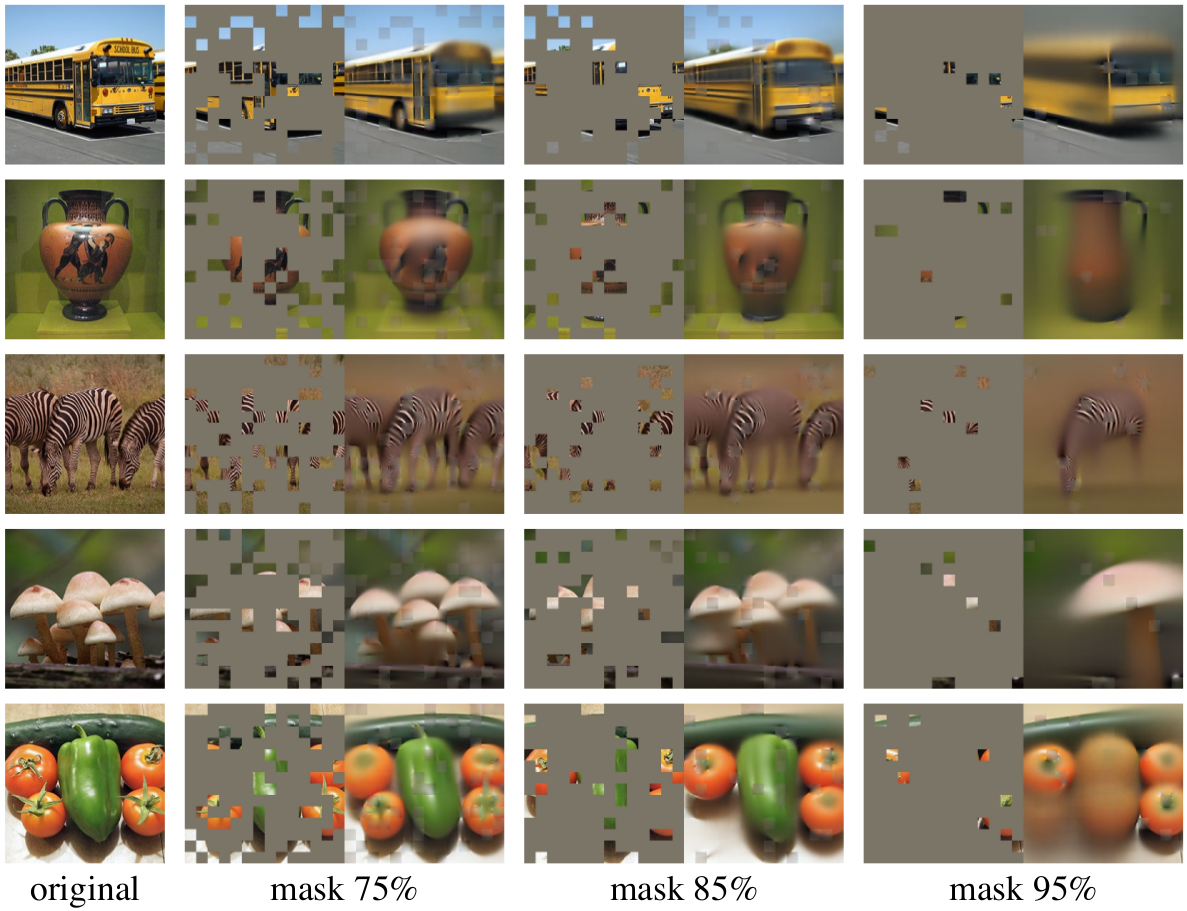 Figure 4. Original image and reconstructions at mask ratios of 75%, 85%, and 95%.
Training duration🔗
The reported accuracy continues to improve through the longest evaluated schedule of 1600 epochs.2
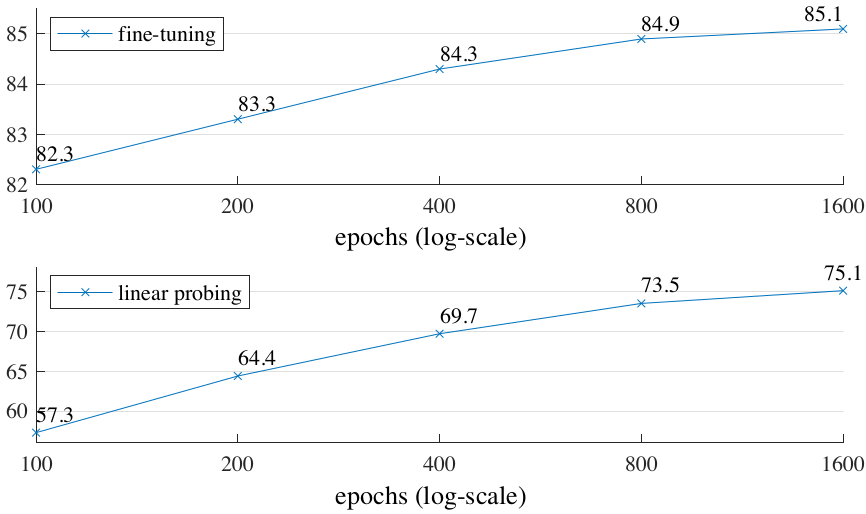 Figure 5. Fine-tuning and linear-probe accuracy improve with longer MAE pretraining in the evaluated 100-to-1600-epoch range.
The result should not be extrapolated indefinitely: the experiment shows improvement up to 1600 epochs, not a general law that every longer schedule must improve accuracy.
Decoder and mask-token ablations🔗
A single Transformer-block decoder still reaches 84.8% after full fine-tuning. One block is the minimum needed for information to propagate between encoded visible tokens and mask tokens. A deeper decoder matters much more for linear probing: increasing decoder depth from one to eight blocks raises linear accuracy from 65.5% to 73.5%.
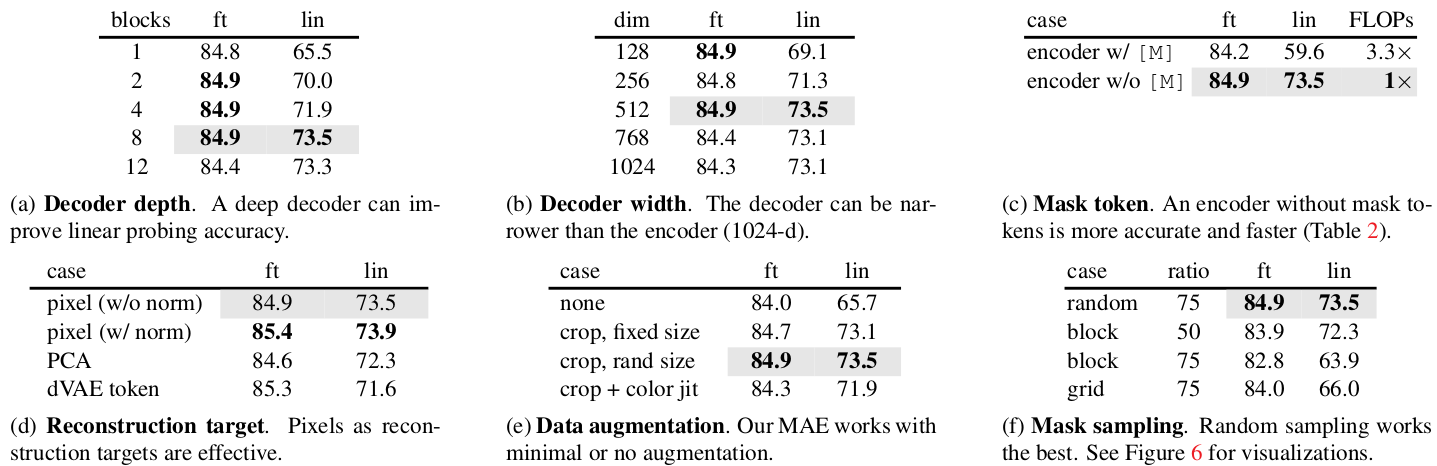 Table 1. MAE ablation experiments with ViT-L/16 on ImageNet-1K.
Keeping mask tokens out of the encoder raises linear-probe accuracy from 59.6% to 73.5%, a 13.9 percentage-point improvement, while fine-tuning rises from 84.2% to 84.9%. It also reduces total training FLOPs by 3.3 times. The associated wall-clock speedup is 2.8 times for the default ViT-L decoder and ranges from 3.5 to 4.1 times in the listed ViT-H or shallow-decoder settings.
Comparison with other self-supervised methods🔗
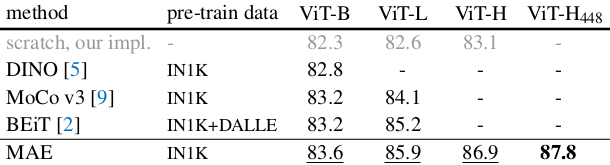
Table 2. ImageNet-1K end-to-end fine-tuning results reported in the MAE paper.
For ViT-B, MAE reaches 83.6%, compared with 82.8% for DINO and 83.2% for both MoCo v3 and BEiT. For ViT-L, MAE reaches 85.9%, compared with 84.1% for MoCo v3 and 85.2% for BEiT; the table does not report DINO at this size. BEiT's discrete tokenizer was pretrained on 250 million DALL-E images, whereas MAE pretraining uses ImageNet-1K alone.
These are end-to-end fine-tuning results. They do not establish that MAE features dominate every method under linear probing or every downstream protocol. Indeed, the paper emphasizes that MAE representations are less linearly separable than MoCo v3 representations.
The 87.8% result uses ViT-H/14, 1600 epochs of ImageNet-1K pretraining, and fine-tuning at \(448\times448\) resolution. MAE is also reported to be 3.5 times faster per pretraining epoch than BEiT.
Partial fine-tuning🔗
Partial fine-tuning updates only the final encoder blocks while freezing the earlier blocks. It provides a useful middle ground between linear probing and end-to-end fine-tuning.
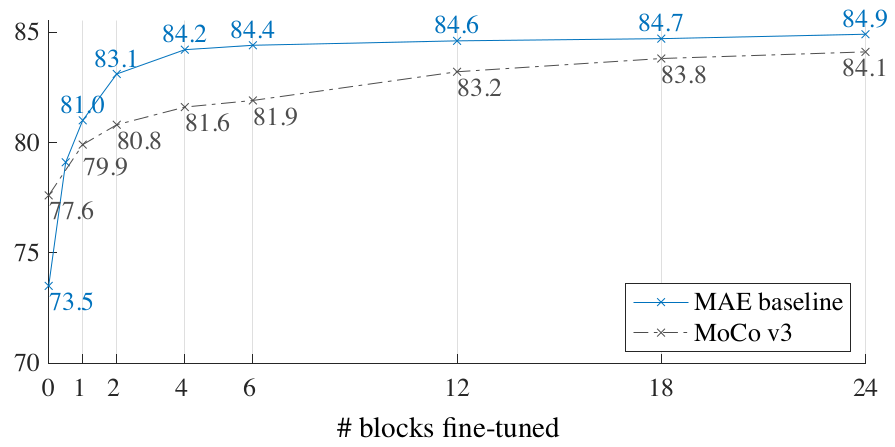
Figure 6. MAE and MoCo v3 accuracy as the number of fine-tuned ViT-L blocks increases.
MAE is less accurate than MoCo v3 under linear probing, but becomes better when at least one Transformer block is fine-tuned. Fine-tuning one block raises MAE accuracy from 73.5% to 81.0%. The broader lesson is that linear separability is not the sole measure of representation quality; MAE learns strong features that benefit from a nonlinear adaptation.
What the reconstructions mean🔗
The masks are random, not selected because the removed patches are semantically insignificant. In fact, the paper notes that random patches are unlikely to form complete semantic segments. Likewise, raw pixels are not semantic entities.
Nevertheless, MAE can produce plausible object- and scene-level reconstructions, including outputs that differ from the exact ground truth. The authors interpret this behavior as evidence that a rich latent representation has emerged. This is a hypothesis supported by qualitative reconstructions and downstream transfer results, not proof that the model explicitly represents named concepts.
The authors argue that MAE's scaling behavior may help move computer-vision pretraining from a predominantly supervised paradigm toward greater use of self-supervision.
Applications🔗
MAE is suited to visual representation pretraining followed by:
- image classification through linear probing or fine-tuning;
- object detection;
- instance segmentation;
- semantic segmentation; and
- transfer to fine-grained or scene-classification datasets.
Benchmark results🔗
The paper evaluates ImageNet-1K classification and several transfer tasks. Comparisons should be interpreted within each table's architecture, pretraining data, and fine-tuning protocol.
Object detection and instance segmentation🔗
The authors fine-tune a ViT-based Mask R-CNN with a feature pyramid network on COCO and report box AP for detection and mask AP for instance segmentation. MAE beats supervised ImageNet-1K pretraining in every listed ViT-B and ViT-L configuration.
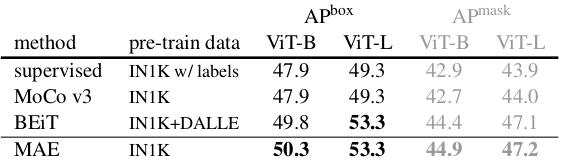
Table 3. COCO object detection and instance segmentation results.
For ViT-L, MAE and BEiT both reach 53.3 box AP, while MAE reaches 47.2 mask AP versus BEiT's 47.1. The pixel-based MAE is therefore better than or effectively on par with token-based BEiT here, while avoiding dVAE tokenizer pretraining.
Semantic segmentation🔗
The paper evaluates semantic segmentation on ADE20K using UperNet.
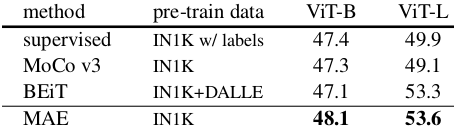
Table 4. ADE20K semantic segmentation results in mean intersection over union.
MAE reaches 48.1 mIoU with ViT-B and 53.6 with ViT-L. The ViT-L result is 3.7 points above supervised pretraining and 0.3 above BEiT.
Classification transfer🔗
The paper additionally reports transfer to iNaturalist 2017, 2018, and 2019, plus Places205 and Places365. These experiments show strong scaling with larger ViT models. At the time of publication, several results exceeded systems pretrained on much larger external datasets, although such system-level comparisons do not isolate pretraining method as the only variable.
Further research🔗
The paper already compares random, block-wise, and grid-wise masks and finds random sampling strongest. Natural extensions include:
- evaluating additional structured or content-aware masking strategies;
- varying the number of visible patches dynamically during pretraining; and
- studying whether mask-ratio schedules change the balance between reconstruction quality, efficiency, and transfer performance.
These are proposed research directions, not claims evaluated in the MAE paper.
Continue through the archive🔗
Compare MAE's pixel-reconstruction objective with DINO's teacher-student agreement. Then see how DINOv2 scales discriminative self-supervision and how I-JEPA predicts missing representations instead of pixels.
Useful resources🔗
- "Masked Autoencoders Are Scalable Vision Learners" - CVPR 2022 paper
- Official MAE implementation
- "Masked Autoencoders Are Scalable Vision Learners" - arXiv
- "BEiT: BERT Pre-Training of Image Transformers"
- "Bootstrap Your Own Latent: A New Approach to Self-Supervised Learning"
- "A Simple Framework for Contrastive Learning of Visual Representations"
- "Momentum Contrast for Unsupervised Visual Representation Learning"
- The first author and project lead of MAE, Kaiming He, was also the first author of Deep Residual Learning for Image Recognition and Momentum Contrast for Unsupervised Visual Representation Learning. ↩︎
- Long ViT training schedules are discussed in How to Train Your ViT? Data, Augmentation, and Regularization in Vision Transformers. A related perspective on long training appears in Knowledge Distillation: A Good Teacher Is Patient and Consistent. These works provide context rather than direct evidence about MAE's mechanism. ↩︎
Comments
comments powered by Disqus