 Michał Chromiak's blog
The DINO paper explained🔗
This article reviews Emerging Properties in Self-Supervised Vision Transformers by Caron et al., published at ICCV 2021.
DINO stands for self-DIstillation with NO labels. It is a self-supervised representation-learning method: it learns from images without human-provided class labels. A student network is optimized by gradient descent to match a teacher network's output for another view of the same image. The teacher has the same architecture but is not trained by backpropagation; its weights are an exponential moving average (EMA) of the student's weights.
The method works with both convolutional networks and Vision Transformers (ViTs), but the paper's most interesting findings concern ViTs. DINO-trained ViTs provide strong image-level features and final-layer self-attention maps that often align with foreground objects and their boundaries.
TL;DR🔗
- DINO is a non-contrastive self-supervised method inspired by self-distillation and momentum-teacher methods such as BYOL and Mean Teacher. It is not simply a successor to SimCLR, MoCo, or BYOL.
- The student and teacher use the same architecture but have different parameters.
- The student processes all augmented views; the teacher processes only the two large global crops.
- Training minimizes cross-entropy between the teacher's probability distribution for one view and the student's distribution for another view.
- The teacher is updated with an EMA of the student and receives no gradients.
- Centering and sharpening act in opposite directions and help prevent representation collapse in the presence of the momentum teacher.
- DINO does not require negative pairs, a contrastive loss, a prediction head, a memory queue, or batch normalization when used with ViT.
- A frozen DINO ViT-S/8 reaches 78.3% ImageNet top-1 accuracy with weighted k-NN. This is not zero-shot classification: the k-NN classifier uses labeled ImageNet training examples.
- DINO ViT-B/8 reaches 80.1% ImageNet top-1 accuracy in linear evaluation.
- Smaller ViT patches improve the reported accuracy without increasing parameter count, but they substantially reduce throughput and increase compute and memory requirements.
- ViT attention maps provide evidence of emergent object localization. They are not explicit semantic segmentation predictions and do not assign semantic classes to pixels.
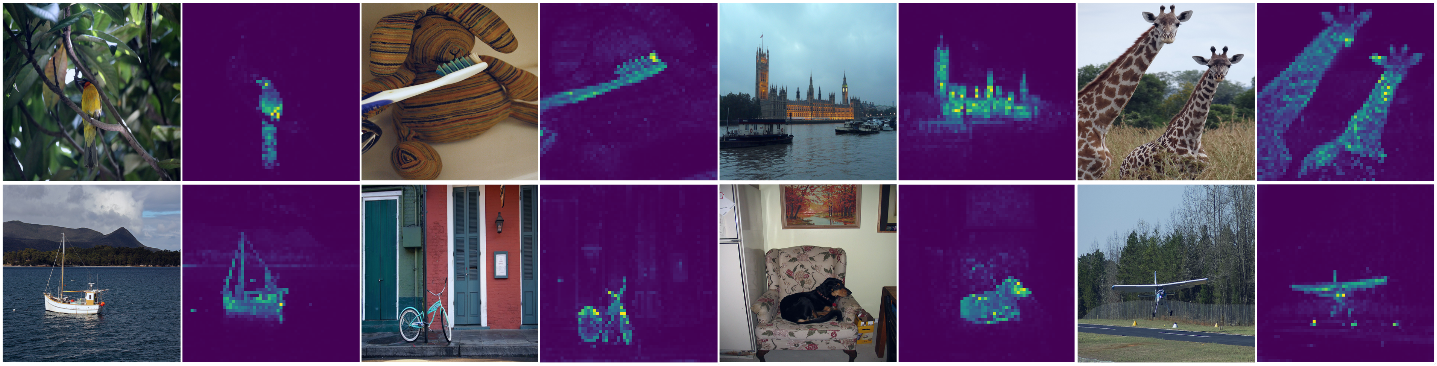 Figure 1. Selected attention heads often focus on foreground objects and align with object boundaries. These are attention maps, not semantic segmentation masks. (Source)
What problem does DINO address?🔗
Supervised image classification compresses the training signal for an image into one label from a fixed vocabulary. Self-supervised learning instead constructs a learning objective from the data itself. The hope is that a model trained without class labels will retain visual information useful across many downstream tasks.
The paper asks what happens when modern self-supervised methods are applied to ViTs. Its central contribution is therefore not a claim that DINO universally replaces supervised ViT training. It is an empirical study showing that:
- self-supervised ViTs can learn image representations that transfer well;
- their frozen features work unusually well with a simple k-NN classifier; and
- their final-layer class-token attention often exposes object layout and boundaries.
The authors also simplify the training recipe. DINO combines a momentum teacher, multi-crop augmentation, cross-view prediction, centering, and sharpening. Unlike many contrastive methods, it does not compare an image against explicit negative examples.
Method🔗
Multiple views of one image🔗
For each training image, DINO creates a set of augmented views:
- two global crops, typically at resolution \(224 \times 224\); and
- several local crops, typically at resolution \(96 \times 96\).
The original implementation uses eight local crops by default. Color jitter, grayscale conversion, Gaussian blur, solarization, and horizontal flipping further alter the views.
This is not a reconstruction objective. Neither network is asked to reproduce the original pixels. Instead, the student must produce a similar high-level output for different crops of the same source image, including local crops that contain only part of the scene.
Student and teacher🔗
Let \(g_{\theta_s}\) be the student and \(g_{\theta_t}\) the teacher. They have the same backbone and projection-head architecture, but their parameters differ.
The student receives every global and local view. The teacher receives only the two global views. For an input view \(x\), the networks produce probability distributions over \(K\) learned output dimensions:
and
Here, \(c\) is the teacher-output center, while \(\tau_s\) and \(\tau_t\) are the student and teacher temperatures. These \(K\) dimensions are learned targets, not human-defined classes.
For each teacher global view \(x\), the student is trained on every other view \(x'\) of the same image:
where \(H(a,b)=-\sum_i a^{(i)}\log b^{(i)}\) is cross-entropy and \(V\) contains all crops. The identical student-teacher view pair is excluded. Gradients flow only through the student.
Momentum teacher🔗
After each student update, the teacher parameters are updated as:
The momentum coefficient \(\lambda\) follows a cosine schedule from 0.996 toward 1. This slowly changing teacher provides more stable targets than using the current student directly. In the paper's ViT-S/16 ablation, removing the momentum teacher causes collapse and yields only 0.1% k-NN and linear accuracy.
Projection head and downstream features🔗
The projection head is a three-layer multilayer perceptron with a 2048-dimensional hidden layer, followed by \(\ell_2\) normalization and a weight-normalized fully connected layer. The self-supervised loss is applied to this head.
For downstream evaluation, the authors discard the projection head and use the frozen backbone representation. For ViTs, this representation is based on the class token.
Figure 2. DINO training overview. The student sees global and local crops; the EMA teacher sees global crops. (Source)
Avoiding collapse🔗
What is representation collapse?🔗
A collapsed network maps many or all inputs to the same output. Such a constant representation can make two augmented views agree perfectly while carrying no useful information about the image.
Contrastive approaches discourage this solution using negative examples. DINO instead combines a momentum teacher with two operations on the teacher output:
- Centering subtracts an EMA of the batch-average teacher logits. It prevents one output dimension from dominating, but by itself tends toward a uniform output distribution.
- Sharpening uses a low teacher temperature to make the teacher distribution more selective. It counters uniform collapse, but by itself can encourage domination by a small number of dimensions.
These effects balance each other. The paper is careful about the scope of this conclusion: centering and sharpening avoid collapse when used with the momentum teacher. They are not demonstrated as a universal collapse-prevention recipe for arbitrary architectures.
The default student temperature is 0.1. For the teacher, the temperature is warmed from 0.04 to 0.07 during the first 30 epochs. The center is also updated by an EMA of teacher outputs.
What emerges in a DINO-trained ViT?🔗
Strong frozen features🔗
The authors evaluate frozen representations in two main ways:
- Linear evaluation: train a supervised linear classifier on top of the frozen features.
- Weighted k-NN evaluation: store frozen features from the labeled ImageNet training set and classify each validation image by a weighted vote among its nearest stored features.
The second protocol is simple, but it is still supervised at evaluation time because it uses labels from the ImageNet training set. Calling it zero-shot would be incorrect.
| Backbone | Patch size | k-NN top-1 | Linear top-1 |
|---|---|---|---|
| ResNet-50 | - | 67.5% | 75.3% |
| ViT-S | \(16 \times 16\) | 74.5% | 77.0% |
| ViT-S | \(8 \times 8\) | 78.3% | 79.7% |
| ViT-B | \(16 \times 16\) | 76.1% | 78.2% |
| ViT-B | \(8 \times 8\) | 77.4% | 80.1% |
The paper generally uses \(k=20\) for weighted k-NN. On the same ViT-S/16 architecture, DINO reaches 77.0% linear accuracy, 3.5 percentage points above the reported SwAV result. Its 74.5% k-NN accuracy is 7.9 points above the best listed BYOL result.
Smaller patches: better spatial detail, higher cost🔗
Reducing the patch size gives the transformer more spatial tokens and improves the reported representation quality. It does not add learned parameters, but self-attention becomes more expensive as the number of tokens grows.
The paper reports throughput of roughly 1007 images/s for ViT-S/16, 180 images/s for ViT-S/8, and 44 images/s for ViT-S/5 under its measurement setup. Smaller patches therefore increase, rather than reduce, running time and memory pressure.
Emergent object localization🔗
In a ViT, the final class token attends to patch tokens. DINO's final-layer attention heads often focus on coherent foreground regions. To quantify this, the authors threshold attention maps to retain 60% of their mass and compare them with object masks from PASCAL VOC 2012.
DINO ViT-S/8 reaches 44.7% Jaccard similarity, compared with 23.7% for supervised ViT-S/8 and 21.8% for a randomly initialized model. This is evidence that object layout emerges in the representation without segmentation labels.
There are important limits to the interpretation:
- Attention maps are not semantic segmentation outputs.
- They do not assign a category to every pixel.
- Different attention heads may focus on different objects or parts.
- The evaluation measures overlap with foreground masks after thresholding; it does not establish a complete segmentation system.
Video object segmentation🔗
The paper also evaluates frozen patch features on DAVIS 2017. Labels are propagated between frames using nearest-neighbor matching; the backbone itself is not fine-tuned for video segmentation. DINO ViT-S/8 obtains 69.9 mean \(J\&F\), compared with 66.0 for supervised ViT-S/8. DINO ViT-B/8 reaches 71.4.
This experiment shows that local patch features encode useful correspondence. It does not mean that raw attention maps alone solve video instance segmentation.
Ablation study🔗
The ViT-S/16 ablation after 300 epochs clarifies which parts of DINO matter:
| Configuration | k-NN top-1 | Linear top-1 |
|---|---|---|
| Default DINO | 72.8% | 76.1% |
| Without momentum teacher | 0.1% | 0.1% |
| Without multi-crop | 67.9% | 72.5% |
| MSE instead of cross-entropy | 52.6% | 62.4% |
| With an added predictor | 71.8% | 75.6% |
The momentum teacher is essential in this setup, and multi-crop training provides a large improvement. Cross-entropy works substantially better than mean squared error. Unlike BYOL, DINO does not benefit from a separate predictor in this experiment.
What DINO does not establish🔗
The paper provides strong evidence for its tested architectures and benchmarks, but some broader conclusions would go beyond the experiments:
- DINO is not a universally superior replacement for supervised learning.
- Its transfer results are strong but not uniformly better on every dataset. For example, supervised ViT-B/16 slightly exceeds DINO on iNaturalist 2018 in the paper's transfer table.
- The learned output dimensions are not automatically named semantic categories.
- k-NN evaluation is not zero-shot learning.
- Attention visualization is evidence of localization, not a production-ready segmentation method.
- The method still requires substantial compute, careful augmentation, and large-scale image data.
Applications🔗
DINO representations are useful when labels are scarce or when a reusable visual encoder is needed. The paper demonstrates or motivates:
- image classification with linear probing, k-NN, or fine-tuning;
- image retrieval and copy detection;
- transfer to classification datasets;
- object discovery through attention analysis; and
- video object segmentation through frozen-feature correspondence.
Relationship to other methods🔗
DINO belongs to a family of methods that learn by matching representations across image views.
- SimCLR uses a contrastive objective with in-batch negatives.
- MoCo uses a momentum encoder and a queue of negative examples.
- BYOL matches an online network to a momentum target network without negatives and uses a predictor.
- SwAV predicts cluster assignments between views and uses online clustering.
- DINO matches centered and sharpened teacher distributions using cross-entropy, a momentum teacher, and multi-crop views, without negatives or a predictor.
DINO can train ResNet-50 as well as ViTs. The paper's distinctive observations, however, are the strong k-NN behavior and emergent spatial structure of self-supervised ViT features.
Useful resources🔗
- ICCV 2021 paper
- DINO on arXiv
- Official PyTorch implementation
- DINO and PAWS overview
- BYOL: Bootstrap Your Own Latent
- Mean Teacher
- MoCo: Momentum Contrast
- DINOv2 explained
Terminology🔗
Knowledge distillation🔗
Knowledge distillation trains a student model to match outputs produced by a teacher. In conventional distillation, the teacher is often a larger, already trained network and the goal may be model compression.
DINO uses self-distillation differently: teacher and student have the same architecture, and the teacher is created continuously as an EMA of the student. There is no separately pretrained teacher and no class-label supervision. The term describes the direction of the learning target, not compression into a smaller model.
Representation collapse🔗
Representation collapse occurs when a network maps different inputs to the same or nearly the same output. Agreement between views then becomes trivial but the features cease to distinguish images. DINO avoids this outcome through the combined training dynamics of its stop-gradient momentum teacher, centering, and sharpening.
Comments
comments powered by Disqus